Back in the 2.1.x announcement post over a whole year ago, one of the bullet points about the upcoming roadmap said we were going to “make you never want to use the VBE’s Project References dialog ever again“; it took a bit longer than expected, but as far as we can tell, this feature does exactly that.
If you’ve been following the project on social media recently, you already know that the next version of Rubberduck will introduce a very exciting, unique new feature: the Reference Explorer dialog, and the addition of a references node in the Code Explorer tree.
Vanilla-VBE
Since forever, adding a reference to the active project in the VBE is a rather… vanilla experience. Functional, but somewhere between bland and tedious.
What’s wrong with it?
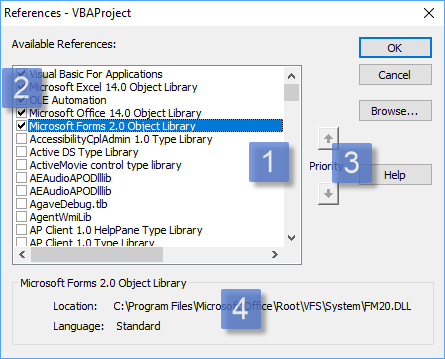
Regardless of what we think of the very 1998-era buttons docked on the side, the dialog works. There’s a list of available libraries (sorted alphabetically), we can browse for unlisted ones, cancel or accept changes, and the libraries that are selected when the dialog is displayed, are conveniently shown at the top of the list!
On a closer look though…
The vanilla-VBE project references dialog
The list of available libraries has the available libraries listed in alphabetical order. You can’t resize the dialog to show more, but you get first-key search. The Scripting runtime’s library name starts with “Microsoft”… which happens to also be the case for a few other libraries; this makes the extremely useful Scripting.Dictionary and Scripting.FileSystemObject classes pretty much hidden until you stumble upon a blog post or a Stack Overflow answer that introduces them.
The selected libraries show up at the top of the list, in priority order. Locked libraries are stacked at the top. You use the up/down arrow buttons to move the selected library up or down, but you can’t move the locked ones.
The priority buttons are used to determine the identifier resolution order; if an identifier exists in two or more libraries, VBA/VB6 binds to the type defined in the library with the highest priority. There’s no visual cue in the list itself to identify the locked-in type libraries, so the Enabled state of these buttons is used to convey that information: you can’t move the locked-in, default references.
The bottom panel is useful… but the path gets cropped if it’s longer than the rather narrow dialog can fit, and you can’t select or copy the text. The actual library version number isn’t shown.
Visual Studio
Let’s take a look at what adding a project reference using the latest version of Microsoft Visual Studio feels like:
The Microsoft Visual Studio 2017 Reference Manager dialog
The dialog can be resized, search is no longer limited to a single character, but still limited to the beginning of the [Name]. The library info is now richer; it moved to the right side, and a panel on the left side determines the contents of the list. Other than that, besides a new [Version] column and a nice dark theme, …the mechanics are pretty much the same as they were 20 years ago: check boxes in a list. Priority is no longer relevant in .NET though – namespaces fixed that.
Rubberduck
This screenshot was taken shortly before the pull request was opened:
The Rubberduck ‘Add/Remove References’ dialog (work in process: release build may differ)
Available libraries appear in a list on the left-hand side of the dialog. Like in Visual Studio, the version number appears next to the library name, and the list is sorted alphabetically. There is no checkbox: instead, the selected library can be moved into the list of referenced libraries.
Referenced libraries appear in a list on the right-hand side of the dialog. Since there is no checkbox, the selected library can be moved back into the list of available libraries.
Priority up/down buttons appear for the selected referenced library, unless it’s locked.
Icons differentiate locked libraries, libraries that were already referenced when the dialog was shown, and libraries that were newly added. In the list of available libraries, recent and pinned libraries have an icon too.
Search works on a “contains” basis, and matches the library name, description, and path. It immediately filters the list of available libraries.
Tabs for quickly accessing type libraries recently referenced, or pinned libraries, or registered. Host-specific project types are in a separate tab, as applicable.
Bottom panel displays the full name and path of the selected type library. The text can be selected and copied into the clipboard.
Browse button allows referencing any project/library that isn’t listed anywhere. If a library can’t be loaded, it will appear in the list as a broken reference, before it’s even tentatively added to the project.
If you haven’t seen it in action yet, here’s a sneak peek:
Of course that’s just the beginning: layout is not completely final, drag-and-drop functionality remains to-do, among other enhancements.
A first iteration of this feature will likely be merged some time next week, and since this is a major, completely new feature, we’ll bump the minor version and that will be Rubberduck 2.4.0, to be released by the end of 2018…
…not too long after the imminent 2.3.1 hotfix release.
If you think this is one of the coolest things a VBE add-in could possibly do, you’re probably not alone. Share the news, and star us on GitHub!
Version 2.2.0 was released in April 2018. Well over 1,700 commits and 2,185 modified files later, Rubberduck is now more stable than ever, and well overdue for a new release. November 25th will see Rubberduck 2.3 issued – as of this writing, we’re ironing a few wrinkles, but everything looks like we’re on track to release some time this Sunday.
A tremendous amount of effort went into the core, the engine, and the brain: the number of situations causing inspection false positives is on a serious decline, and we’ve taken very important steps towards ensuring proper tear-down of every component. Rubberduck 2.3 is by far the most stable release to date, and all the invisible work lays the foundation for the very exciting things to come.
We’re all extremely proud to present the results of so many months of hard work! Here’s a non-exhaustive overview of the new features (versus 2.2.0).
Official VB6 IDE Support
As of v2.3.0 (with special thanks to @mansellan), Rubberduck officially works in Visual Studio 6.0, the glorious, the… legendary VB6 IDE.
That’s right: code inspections, code metrics, all navigation enhancements, unit testing, refactorings, …all your favorite Rubberduck features, in the Visual Basic 6.0 editor.
This is without a doubt the biggest improvement to ever come to the VB6 IDE this century, from an open-source project.
As is the case for VBA hosts, if you already have Smart Indenter installed, Rubberduck will detect the legacy 32-bit add-in and prompt to import your settings – note that configuring Rubberduck’s indenter will not affect your Smart Indenter settings.
Autocompletion Enhancements
Rubberduck now changes how typing code in the editor feels. If you ever edited VBA/VB6 code in Notepad++ (let alone VB.NET code in the latest Visual Studio), you know that the VBE shows its age when you type a " double quote or open a ( parenthesis. With Rubberduck, typing code in the VBE will now feel radically different than without, in a very good way. A new dedicated settings page makes it easy to enable/disable each feature separately, and leaves room for future customization and enhancements.
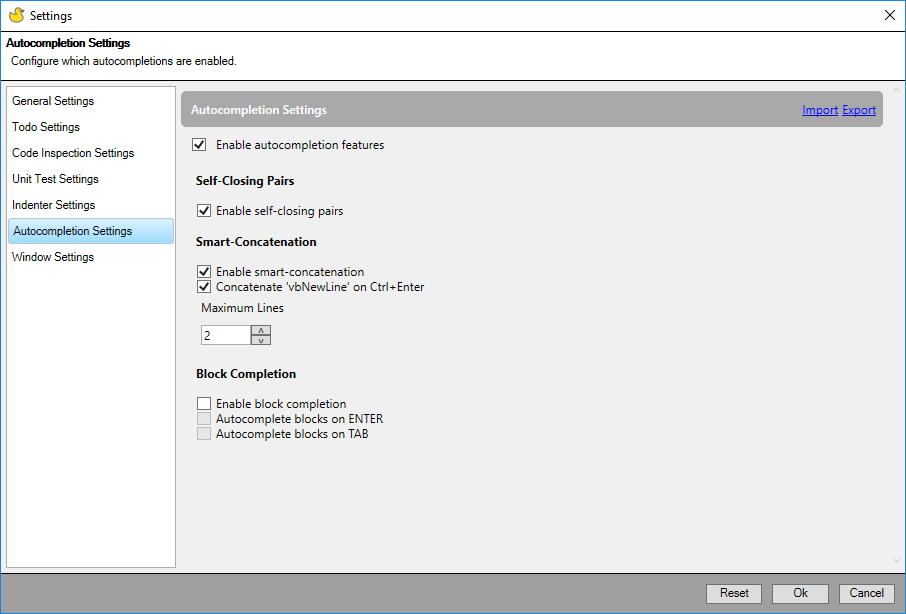
Due to its rather invasive nature, a design decision was made to ship autocompletion features disabled by default; these features must be enabled manually, in the autocompletion settings tab of Rubberduck’s “Settings” dialog:
Self-Closing Pairs
It’s hard to describe everything enabling SCP completion does. A picture is worth a thousand words, so… how about seeing them in action?
When {BACKSPACE} is pressed and the caret immediately follows any opening token, Rubberduck attempts to locate and remote the matching closing token, wherever it is on the current logical line of code – nested or not.
Smart Concatenation
When enabled, Rubberduck will step in when the {ENTER} key is pressed while the caret is inside a string literal, to automatically append ” & _” to the current line.
The feature can also be configured so that when the {CTRL} key is held down when {ENTER} is pressed, ” & vbNewLine & _” will be appended to the current line.
{BACKSPACE} cleanly reverts smart-concatenation when the caret is on the last line of the logical code line and the caret line contains nothing but the opening & closing quotes.
Block Completion
Block completion will be implemented early in the 2.3.x cycle: these settings have no effect whatsoever for now.
The vision for this feature, is to capture “trigger” keywords (e.g. For), select them; if {TAB} or {ENTER} is pressed (as configured) when the “trigger” is selected (among other conditions), then the block expands, and Rubberduck automatically highlights a placeholder expression; hitting {TAB} again selects the next placeholder, {SHIFT}+{TAB} the previous. Providing a value for the last placeholder places the caret inside the block, indented as per indenter settings.
Auto-correct
Later in the 2.3.x cycle, auto-completion will be further enhanced with an “auto-correct” feature, which will enable automatically expanding e.g. foo++ into foo = foo + 1, among other ideas… including automatic fixing of a configurable list of “frequent typos”.
New Inspections
As with every new Rubberduck release, the team implemented a number of new inspections. This release introduces an internal API for code path analysis, which allows us to start implementing the more involved inspections on our plate!
These new inspections bring the total number to 75!
AssignmentNotUsed
The first inspection to leverage code path analysis, will now flag this code:
foo = 42 ' <~ value is never used
foo = 10
Debug.Print foo
When an assignment is subsequently discarded before the stored value is accessed, Rubberduck will notify about the redundant assignment, as a code quality issue.
DuplicatedAnnotation
This inspection, spliced from the existing “illegal annotation” inspection, helps validate/sanitize Rubberduck annotations – for example, contradicting @Folder annotations:
'@Folder("Foo")
'@Folder("Bar")
ExcelUdfNameIsValidCellReference
An Excel-specific inspection that flags public functions that are visible as worksheet user-defined functions (UDF), but shadowed by a cell reference. This inspection is particularly useful with recent 64-bit versions of Microsoft Excel, where 16,384 columns effectively reserve every 3-letter combination up to “XFC”.
Public Function Foo123() As String
'FOO123 is a valid cell reference; function cannot be invoked!
End Function
This first iteration only inspects public functions in standard procedural modules.
IsMissingOnInappropriateArgument
A rather specific inspection validating usages of IsMissing, flagging instances where the function is given a non-Variant argument.
Public Sub DoSomething(Optional ByVal foo As String)
    If IsMissing(foo) Then ' condition is always false
    End If
End Sub
IsMissingWithNonArgumentParameter
Another inspection validating usages of IsMissing, flagging instances where the function is given a non-parameter argument.
Public Sub DoSomething()
    Dim foo As Variant
    If IsMissing(foo) Then ' condition is always false
    End If
End Sub
ObsoleteCallingConvention
CDecl calling convention isn’t supported on Windows; Declare statements using it should be wrapped with conditional compilation directives so as to only compile in a Mac environment.
Private Declare Sub Beep CDecl Lib "kernel32" (dwFreq As Any, dwDuration As Any)
ObsoleteMemberUsage
Rubberduck 2.3 introduces a new @Obsolete annotation, which can be used for annotating “obsolete” procedures – the inspection flags usages of procedures marked with this annotation.
OnLocalError
The Local token is redundant in On Error statements. This inspection flags usages.
Private Sub DoSomething()
    On Local Error GoTo ErrHandler
    '...
    Exit Sub
ErrHandler:
End Sub
The rationale being, runtime errors are always local; the two syntaxes look different but do exactly the same thing.
v2.3.x
There are a number of features that were intended to be developed for 2.2.x, that didn’t make it into this release – not because the ideas were dropped, but because of mere time constraints. The add/remove references dialog is one such feature. Keep an eye out on 2.3.x pre-release builds and announcements; the v2.4 announcement will recap everything that happened in 2.3.x, but every new feature will very likely see its own dedicated blog post as it is merged and pre-released.
A few months ago I merrily announced the first Rubberduck feature that actively interfered with typing code in the VBE. It wasn’t the first opportunity though: a rather long time ago, I flirted with the idea of triggering a parse task at every keypress, so that Rubberduck’s parse trees would always be up-to-date – but back then the parse task cancellation mechanics weren’t as fine-tuned as they are now, and it ended up being a bad idea. Interfering with typing in any way that introduces any kind of lag, or exacerbates a memory leak, can only be a bad idea.
But auto-completion was different. If done right, it would be the single best thing to happen to the VBE since Smart Indenter came along, two decades ago. So in less than two weeks I whipped up something I thought would work, got ecstatic over how awesome seeing blocks automatically completing, I announced the feature… and as feedback from the pre-release builds started coming in as bug reports, I started to realize the reason why no other VBE add-in offered a feature like this: the feature is far from trivial, and any mistake or oversight means interfering with typing code in an utterly annoying and disrupting way – the margin for error is very thin, as is the fine line between being incredibly intuitive & helpful, and being a complete pain in the neck.
The VBIDE API wasn’t made for this. The VBE wasn’t made to be extended that way.
But I’m not letting that stop me.
So I scrapped most of my hasty work, went back to the drawing board, rolled up my sleeves, and started over. At the time of this writing, block completion still hasn’t gotten the attention it deserves, for I decided to start round 2 with self-closing pairs.
As of this writing, I can confidently say that the feature is going to be rock-solid.
Fighting the VBE
The Visual Basic Editor has a soul of its own. And when you twist its arm, it slaps you back at every chance it has. To fight it, you need to know how it moves. You can’t prevent its mischievous deeds; to win, you need to embrace them, anticipate them. The extensibility API won’t let us inject a single character on the current line of code: we need to replace the entire line – and then dance with the devil.
With the code panes subclassed to pick up keystrokes, VBENativeServices fires up an event that the AutoCompleteService handles (assuming settings have autocompletion enabled – failing which the event isn’t even fired). At this point if the IntelliSense drop-down is shown or the current selection isn’t at a single-character position, we immediately bail out. Otherwise, we run the self-closing pairs feature proper.
Cue Eye of the Tiger backing track…
Know where you are
We need to get the integral text of the current logicalline of code (i.e. accounting for line continuations), take note of the caret position relative to the beginning of this logical line of code; take note of the line position relative to line 1 of the module as well – we encapsulate this data into a CodeString – a class that represents a logical line of code, a caret position in that logical line, with the position of this logical line in the module: that’s the original, and only the first real punch…
Know where the VBE is
The original is a trap though. If you don’t tread carefully here, you’ll take a serious one in the ribs. The problem is that because the original code is currently being edited, it’s e.g. “msgbox|” (where | would be the caret), if the keypress was " then when you mean to write “msgbox"|"” by replacing the entire current line of code, the VBE inserts that string but then the caret is now on the next line and you need to explicitly set the ICodePane.Selection value. Now dodge this: between the moment you replace the current line msgbox with msgbox"" and by the next moment you want to place the caret back to msgbox"|", if you skipped a step you have an uppercut to dodge, for at that point what’s really in the VBE is MsgBox "", so the caret ends up here: MsgBox |"". If you counter with offsetting the caret position by one, you just broke the case where the user would have typed that whitespace: msgbox "" would be off by one also: MsgBox ""|.
The solution is Judoesque: let the VBE come at you with everything it can. Embrace the flames. Fight fire with fire. The whole “prettification” trick is encapsulated in a specialized ICodeStringPrettifier object, whose role is to tell the VBE to bring it.
Hit me with your best shot. To work out the “prettified” version of the code, we determine the original caret position in terms of non-whitespace character count. Then we make the VBE modify the code, get the new prettifiedCode, and the caret position we want to be at should be at the index of the nth non-whitespace character, where n is the original count. And that should get us out of trouble.
The only problem is that we don’t know which self-closing pair we’re dealing with, so it’s too early do intervene now – now that we know where the VBE stands, we need to know if we want to deliver a left or a right.
Find an opening
Once we know which SelfClosingPair to test for a result, it’s still too early to pull the prettifier trick – first we need to be sure our pair produces an output given the input, so we Execute it once, against the original code. If the pair returns a result, then we get the prettified original caret position… that way we don’t ruin the show by swinging into the void 3 times for every one time we land a hit.
One-Two
If we just hit once with everything we’ve got, the VBE will beat us again. We need a combo. First we replace the current logical line (“snippet”) with the result we got from the second Execute of the pair, which ran off the prettifier code:
result = scpService.Execute(selfClosingPair, prettified, e.Character);

module.DeleteLines(result.SnippetPosition);
module.InsertLines(result.SnippetPosition.StartLine, result.Code);
Here the VBE will prettify again, so you need to take it by surprise with a second blow – if the re-prettified code isn’t the code we’ve just written to the code pane, then we’re likely off by one and the final Selection will have to be offset:
var reprettified = module.GetLines(result.SnippetPosition);
var offByOne = result.Code != reprettified;
var finalSelection = new Selection(result.SnippetPosition.StartLine,
                                   result.CaretPosition.StartColumn + 1)
                     .ShiftRight(offByOne ? 1 : 0);
pane.Selection = finalSelection;
If we dodged every bullet up to this point, we win… round 1.
Round 2: Backspace
Handling the pair-opening character is one thing, handling the pair-closing character is trivial. Handling backspace is fun though: we get to locate the matching character for our pair, and make both the opening and closing characters to be removed from the logical code line that we write back. Round 2 is just as riveting as round 1!
So if you have this:
foo = (| _
    (2 + 2) + 42
)
If the next keypress is BACKSPACE then you get this:
foo = | _
(2 + 2) + 42
Or given this:
foo = ( _
    (|2 + 2) + 42
)
You’d get:
foo = ( _
    2 + 2 + 42
)
We won’t be handling the DELETE key, but we’re not done yet: we can deliver another blow.
Round 3: Smart Concatenation
By handling the ENTER key and knowing whether the CTRL key was also pressed, we can turn this:
MsgBox "Lorem ipsum dolor sit amet,|"
if the next keypress is ENTER, into this:
MsgBox "Lorem ipsum dolor sit amet," & _
       "|"
and if the next keypress is CTRL+ENTER, into this:
MsgBox "Lorem ipsum dolor sit amet," & vbNewLine & _
       "|"
The VBE will only fight back with a compile error if the logical line of code contains too many line continations. We don’t have anything to do: the VBIDE API will throw an error, but Rubberduck’s wrappers simply catch that COM exception, making the line-insert operation no-op: the new line ends up not being added, no annoying message box, and the caret ends up on the next line, at the same indent.
Ding Ding Ding!
Rubberduck wins this fight for self-closing pairs, but the VBE will be back for more soon enough: it is anticipated to put up a good fight for block completion as well…
If you recall the AIPlayer class from Part 2, the Create factory method takes an IGameStrategy parameter:
Public Function Create(ByVal gridId As Byte, ByVal GameStrategy As IGameStrategy) As IPlayer
    With New AIPlayer
        .PlayerType = ComputerControlled
        .GridIndex = gridId
        Set .Strategy = GameStrategy
        Set .PlayGrid = PlayerGrid.Create(gridId)
        Set Create = .Self
    End With
End Function
An AIPlayer can be created with an instance of any class that implements the IGameStrategy interface.
In any OOP language that supports class inheritance, we could have a base class e.g. GameStrategyBase, from which we could derive the various implementations, and with that we would have a place to write all the code that’s common to all implementations, …or that all implementations would possibly need to use… or not. See, class inheritance is the most important language feature that the “VBA can’t do OOP” or “VBA is not a real language” crowd love to bring up. And yet, more often than not, class inheritance isn’t the ideal solution – composition is.
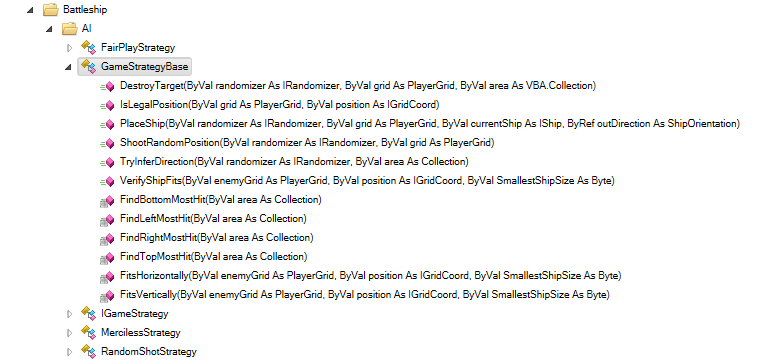
And we’re going to do exactly that, by composing all IGameStrategy implementations with a GameStrategyBase class:
Coupling a game strategy with this “base” class isn’t an issue: the class is specifically meant to be used by IGameStrategy implementations. So we can shamelessly do this:
Option Explicit
Implements IGameStrategy
Private base As GameStrategyBase

Private Sub Class_Initialize()
    Set base = New GameStrategyBase
End Sub
And then proceed with implementing the PlaceShip method, given that AI player’s own PlayerGrid and the IShip the game controller is asking us to place on the grid. The base.PlaceShip method simply returns the first legal position+direction it can find.
Then we can implement the Play function to return an IGridCoord position and let the controller know what position this player is shooting at. We have a number of helper functions in GameStrategyBase we can use for that.
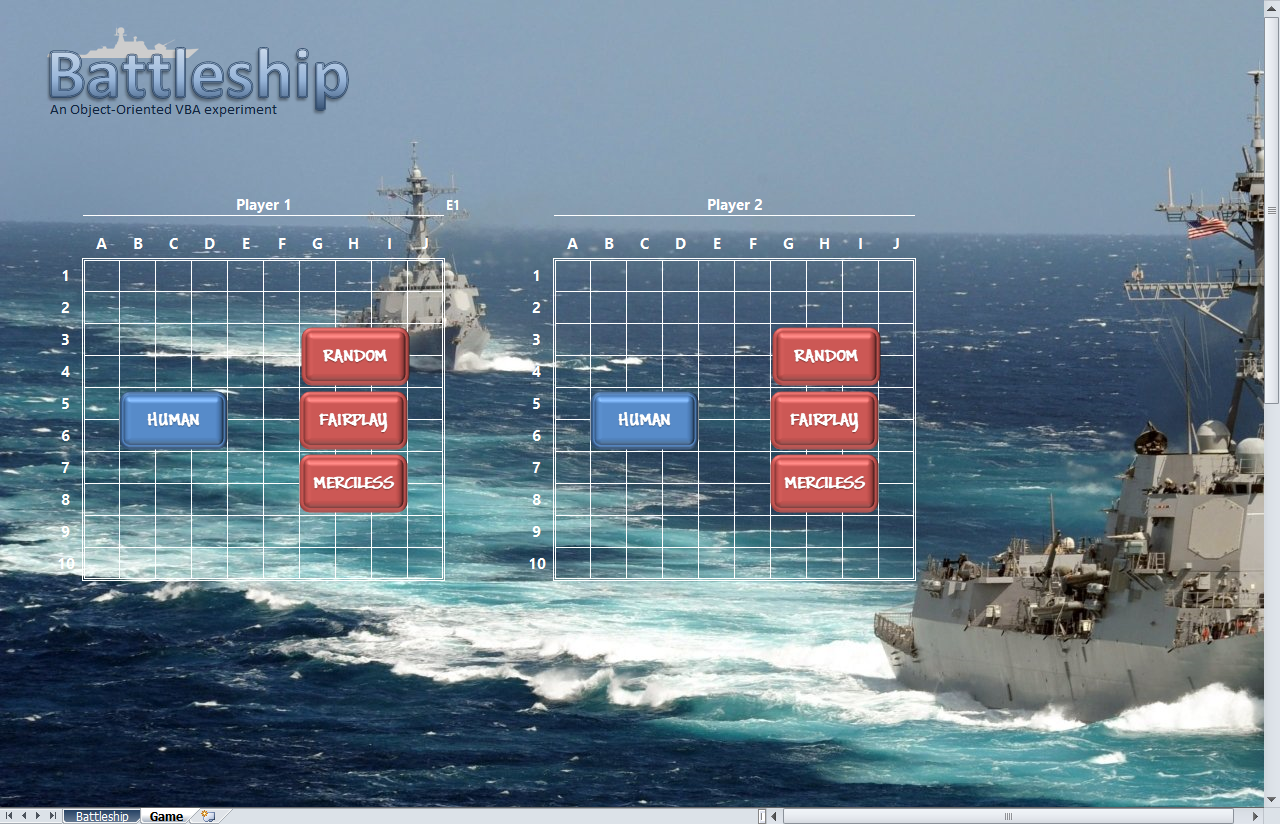
Random
The RandomShotStrategy shoots at random coordinates until it has located all enemy ships …then proceeds to sink them all, one after the other. It also places its ships randomly, regardless of whether the ships are adjacent or not.
Private Sub IGameStrategy_PlaceShip(ByVal grid As PlayerGrid, ByVal currentShip As IShip)

    Dim direction As ShipOrientation
    Dim position As IGridCoord
    Set position = base.PlaceShip(Random, grid, currentShip, direction)

    grid.AddShip Ship.Create(currentShip.ShipKind, direction, position)
    If grid.shipCount = PlayerGrid.ShipsPerGrid Then grid.Scramble

End Sub

Private Function IGameStrategy_Play(ByVal enemyGrid As PlayerGrid) As IGridCoord
    Dim position As IGridCoord
    Do
        If EnemyShipsNotAcquired(enemyGrid)  0 Then
            Set position = base.ShootRandomPosition(Random, enemyGrid)
        Else
            Set position = base.DestroyTarget(Random, enemyGrid, enemyGrid.FindHitArea)
        End If
    Loop Until base.IsLegalPosition(enemyGrid, position)
    Set IGameStrategy_Play = position
End Function
Here the double-negative in the statement “the number of enemy ships not acquired, is not equal to zero” (WordPress is having a hard time with rendering that operator, apparently), will probably be end up being inverted into a positive statement, which would make it read better. Perhaps If EnemyShipsToFind = 0 Then, and invert the Else logic. Or…
Private Function IGameStrategy_Play(ByVal enemyGrid As PlayerGrid) As IGridCoord
    Dim position As IGridCoord
    Do
        If EnemyShipsToFind(enemyGrid) > 0 Then
            Set position = base.ShootRandomPosition(Random, enemyGrid)
enemyGrid.FindHitArea)
        Else
            Set position = base.DestroyTarget(Random, enemyGrid,
        End If
    Loop Until base.IsLegalPosition(enemyGrid, position)
    Set IGameStrategy_Play = position
End Function
That EnemyShipsToFind function should probably be a member of the PlayerGrid class.
FairPlay
The FairPlayStrategy is similar, except it will proceed to destroy an enemy ship as soon as it’s located. It also takes care to avoid placing ships adjacent to each other.
Private Sub IGameStrategy_PlaceShip(ByVal grid As PlayerGrid, ByVal currentShip As IShip)
    Do
        Dim direction As ShipOrientation
        Dim position As IGridCoord
        Set position = base.PlaceShip(Random, grid, currentShip, direction)

    Loop Until Not grid.HasAdjacentShip(position, direction, currentShip.Size)

    grid.AddShip Ship.Create(currentShip.ShipKind, direction, position)
    If grid.shipCount = PlayerGrid.ShipsPerGrid Then grid.Scramble
End Sub

Private Function IGameStrategy_Play(ByVal enemyGrid As PlayerGrid) As IGridCoord
    Dim position As GridCoord
    Do
        Dim area As Collection
        Set area = enemyGrid.FindHitArea

        If Not area Is Nothing Then
            Set position = base.DestroyTarget(Random, enemyGrid, area)
        Else
            Set position = base.ShootRandomPosition(Random, enemyGrid)
        End If
    Loop Until base.IsLegalPosition(enemyGrid, position)
    Set IGameStrategy_Play = position
End Function
Merciless
The MercilessStrategy is more elaborate: it doesn’t just shoot at random – it shoots in patterns, targeting the edges and/or the center areas of the grid. It will destroy an enemy ship as soon as it’s found, and will avoid shooting in an area that couldn’t possibly host the smallest enemy ship that’s still afloat. And yet, it’s possible it just shoots a random position, too:
Private Sub IGameStrategy_PlaceShip(ByVal grid As PlayerGrid, ByVal currentShip As IShip)
    Do
        Dim direction As ShipOrientation
        Dim position As IGridCoord
        Set position = base.PlaceShip(Random, grid, currentShip, direction)
    Loop Until Not grid.HasAdjacentShip(position, direction, currentShip.Size)

    grid.AddShip Ship.Create(currentShip.ShipKind, direction, position)
    If grid.shipCount = PlayerGrid.ShipsPerGrid Then grid.Scramble
End Sub

Private Function IGameStrategy_Play(ByVal enemyGrid As PlayerGrid) As IGridCoord
    Dim position As GridCoord
    Do
        Dim area As Collection
        Set area = enemyGrid.FindHitArea

        If Not area Is Nothing Then
            Set position = base.DestroyTarget(Random, enemyGrid, area)
        Else
            If this.Random.NextSingle < 0.1 Then
                Set position = base.ShootRandomPosition(this.Random, enemyGrid)
            ElseIf this.Random.NextSingle < 0.6 Then
                Set position = ScanCenter(enemyGrid)
            Else
                Set position = ScanEdges(enemyGrid)
            End If
        End If

    Loop Until base.IsLegalPosition(enemyGrid, position) And _
               base.VerifyShipFits(enemyGrid, position, enemyGrid.SmallestShipSize) And _
               AvoidAdjacentHitPosition(enemyGrid, position)
    Set IGameStrategy_Play = position
End Function
In most cases (ScanCenter and ScanEdges do), the AI doesn’t even care to “remember” the last hit it made: instead, it asks the enemy grid to give it a “hit area”. It then proceeds to analyze whether that area is horizontal or vertical, and then attempts to extend it further.
I got nerd-sniped. A Rubberduck user put up a feature request on the project’s repository, and I thought “we need this, yesterday”… so I did it, and the result crushed all the expectations I had – the prerelease build is here!
There are a few quirks – but rule of thumb, it’s fairly stable and works pretty well. Did you see it in action?
This feature rather impressively enhances the coding experience in the VBE – be it only with how it honors your Rubberduck/Smart Indenter settings to literally auto-indent code blocks as you type them.
Writing auto-completing VBA code, especially with auto-completing double quotes and parentheses, gives an entirely fresh new feel to the good old VBE… I’m sure you’re going to love it.
And in case you don’t, you could always cherry-pick which auto-completions you want to use, and which ones you want to disable:
Inline Completion
These work with the current line (regardless of whether you’re typing code or a comment, or whether you’re inside a string literal), by automatically inserting a “closing” token as soon as you type an “opening” token – and immediately puts the caret between the two. These include (pipe character | depicts caret position):
String literals: " -> "|"
Parentheses: ( -> (|)
Square brackets: [ -> [|]
Curly braces: { -> {|}
Block Completion
These work with the previous line, immediately after committing it: on top of the previous line’s indentation, a standard indent width (per indenter settings) is automatically added, and the caret is positioned exactly where you want it to be. These include (for now):
Do -> Do [Until|While]...Loop
Enum -> Enum...End Enum
For -> For [Each]...Next
If...Then -> If...Then...End If
#If...Then -> #If...Then...#End If
Select Case -> Select Case...End Select
Type -> Type...End Type
While -> While...Wend
With...End With
On top of these standard blocks, On Error Resume Next automatically completes to ...On Error GoTo 0.
Quirks & Edge Cases
It’s possible that parenthesis completion interferes with e.g. Sub() statements (an additional opening parenthesis is sometimes added). This has been experienced and reproduced, but not consistently. If you use the feature and can reliably reproduce this glitch, please open an issue and share the repro steps with us!
On Error Resume Next will indent its body, but there currently isn’t any indenter setting for this: we need to add an indenter option to allow configuring whether this “block” should be indented or not.
Deleting or back-spacing auto-completed code may trigger the auto-complete again, once.
Line numbers are ignored, and an opening token found on the last line of a line-continuated comment will trigger a block auto-complete.
Lastly, care was taken to avoid completing already-completed blocks, however if you try hard enough to break it, you’ll be able to generate non-compilable code. Auto-completion cannot leverage the parser and only has a very limited string view of the current/committed line of code. The nice flipside of this limitation, is very nice performance and no delays in your typing.
None of these issues outweight the awesomeness of it, so all auto-completions are enabled by default.
The last “green” release was a couple of months ago already – time to take a step back, look at all we’ve done, and call it a “minor” update.
What’s up duck?
Functionality-wise, not much. Bug fixes, yes; this means fewer inspection false positives, fewer caching accidents, overall more stable usage. But this time some serious progress was also made in the COM & RCW management area, and Rubberduck 2.2 no longer crashes on exit, or leave a dangling host process, or brick the VBE on reload. Some components are still stubbornly refusing to properly release, so unload+reload is still a not-recommended thing to do, but doing so no longer causes access violations. Which is neat, because this particular problem had been plaguing Rubberduck since the early days of 2.0.
Source Control Disintegration
If you haven’t been following the project since v2.1 was released, you may be disappointed to learn that we are officially dropping the source control integration feature. Not saying it’ll never resurface, but the feature was never really stable, and rather than drain our limited resources on a nice but non-essential feature, we focused on the “core” stuff for now. So instead of keeping the half-baked, half-broken thing in place, we removed it – entirely, so there’s 0 chance any part of it interferes with anything else (there were hooks in place, handling parser state changes and some VBE events).
The “Export Project” functionality remains though, so you can still use your favorite source control provider (Git, SVN, Mercurial, etc.) – Rubberduck just isn’t providing a UI to wrap that provider’s functionality anymore.
Shiny & New
We have new inspections! Rubberduck can now tell you when a Case block is semantically unreachable. Or when For loops specify a redundant Step 1, or if you prefer having an explicit Step clause everywhere, it can tell you about that too. Another inspection warns about error-handling suppression (On Error Resume Next) that is never restored (On Error GoTo 0). If you’re unfortunate enough to encounter the thoroughly evil Def[Type] statements, you’ll be relieved to know that Rubberduck will now warn you about implicitly typed identifiers.
Code Metrics is an entirely new tool, that evaluates cyclomatic complexity and nesting levels of each method and module. The feature clearly needs some UI work (wink wink, nudge nudge, C#/WPF reader), and enhancement ideas are always welcome.
The unit test execution engine no longer invokes the host application. There’s a bit of black magic going on here, but to keep it simple, the unit testing feature now works in every single VBE host application.
But the most spectacular changes aren’t really tangible, user-facing things. We’ve streamlined settings, upgrated our grammars from Antlr4.3 to Antlr4.6 – which fixed a number of parser issues, including significant performance improvements when parsing long Boolean expressions; the IInspection interface was fine-tuned again, COM object references were removed in a number of critical places. If you have a fork of the project, you already know that we’ve split Rubberduck.dll into Rubberduck.Core.dll and Rubberduck.Main.dll, with the entry point and IoC configuration in ‘Main’.
Oh, I lied. One of the most spectacular changes is atangible, user-facing thing. It’s just not exactly in the main code base, is all. Poor installer, always gets left behind.
Administrative Privileges no longer needed!
Since a couple of pre-release builds, the Rubberduck installer supports per-user installs that no longer require admin privs. This means Rubberduck can now be installed on a locked-down workstation, without requiring IT intervention! This revamped installer also detects and properly uninstalls a previous Rubberduck install (admin elevation would be required to uninstall a per-machine installation of a previous build though), so manually uninstalling through the control panel before upgrading, is no longer recommended/needed. Doesn’t hurt, but shouldn’t change anything, really.
The “installating / instructions” and “contributing / initial setup” wiki pages have been updated accordingly on GitHub.
This new installer no longer assumes Microsoft Office is present, and registers for both 32 and 64-bit host applications.
That’s it? What happened to the rest of 2.1.x?
I did say “minor update”, yeah? The previously announced roadmap for 2.1.x was too ambitious, and not much of it is shipping in this release. In fact, that roadmap should have said “2.x”… versioning is hard, okay? If we stuck to 2.1.x, then a v2.2 would have been moot, since by then we would have had much of 3.0 in place.
Anyway, 2.2 is a terrific improvement over 2.1, on many levels – and that can only mean one thing: that the current development cycle will inevitably lead to even more awesomeness!
The key to writing clear, unambiguous code, is rather simple:
Do what you say; say what you do.
VBA has a number of features that make it easy to not even realize you’re writing code that doesn’tdo what it saysit does.
One of the reasons for that, is the existence of default members – under the guise of what appears to be simpler code, member calls are made implicitly.
If you know what’s going on, you’re probably fine. If you’re learning, or you’re just unfamiliar with the API you’re using, there’s a trap before your feet, and both run-time and compile-time errors waiting to happen.
It’s adding a Range object, using the String representation of Range.[_Default] as a key. That’s two very different things, done by two bits of identical code. Clearly that snippet does more than just what it claims to be doing.
Discovering Default Members
One of the first classes you might encounter, might be the Collection class. Bring up the Object Browser (F2) and find it in the VBA type library: you’ll notice a little blue dot next to the Item function’s icon:
Whenever you encounter that blue dot in a list of members, you’ve found the default member of the class you’re looking at.
That’s why the Object Browser is your friend – even though it can list hidden members (that’s toggled via a somewhat hidden command buried the Object Browser‘s context menu), IntelliSense /autocomplete doesn’t tell you as much:
Rubberduck’s context-sensitive toolbar has an opportunity to display that information, however that wouldn’t help discovering default members:
Until Rubberduck reinvents VBA IntelliSense, the Object Browser is all you’ve got.
What’s a Default Member anyway?
Any class can have a default member, and only one single member can be the default.
When a class has a default member, you can legally omit that member when working with an instance of that class.
In other words, myCollection.Item(1) is exactly the same as myCollection(1), except the latter is implicitly invoking the Item function, while the former is explicit about it.
Can my classes have a default member?
You too can make your own classes have a default member, by specifying a UserMemId attribute value of 0 for that member.
Unfortunately only the Description attribute can be given a value (in the Object Browser, locate and right-click the member, select properties) without removing/exporting the module, editing the exported .cls file, and re-importing the class module into the VBA project.
An Item property that looks like this in the VBE:
Public Property Get Item(ByVal index As Long) As Variant
End Property
Might look like this once exported:
Public Property Get Item(ByVal index As Long) As Variant
Attribute Item.VB_Description = "Gets or sets the element at the specified index."
Attribute Item.VB_UserMemId = 0
End Property
It’s that VB_UserMemId member attribute that makes Item the default member of the class. The VB_Description member attribute determines the docstring that the Object Browser displays in its bottom panel, and that Rubberduck displays in its context-sensitive toolbar.
Whatever you do, DO NOT make a default member that returns an instance of the class it’s defined in. Unless you want to crash your host application as soon as the VBE tries to figure out what’s going on.
What’s Confusing About it?
There’s an open issue (now closed) detailing the challenges implicit default members pose. If you’re familiar with Excel.Range, you know how it’s pretty much impossible to tell exactly what’s going on when you invoke the Cells member (see Stack Overflow).
You may have encountered MSForms.ReturnBoolean before:
Private Sub ComboBox1_KeyPress(ByVal KeyAscii As MSForms.ReturnInteger)
If Not IsNumeric(Chr(KeyAscii)) Then KeyAscii = 0
End Sub
The reason you can assign KeyAscii = 0and have any effect with that assignment (noticed it’s passed ByVal), is because MSForms.ReturnInteger is a class that has, you guessed it, a default member – compare with the equivalent explicit code:
Private Sub ComboBox1_KeyPress(ByVal KeyAscii As MSForms.ReturnInteger)
If Not IsNumeric(Chr(KeyAscii.Value)) Then KeyAscii.Value = 0
End Sub
And now everything makes better sense. Let’s look at common Excel VBA code:
Dim foo As Range
foo = Range("B12") ' default member Let = default member Get / error 91
Set foo = Range("B12") ' sets the object reference '...
If foo is a Range object that is already assigned with a valid object reference, it assigns foo.Value with whatever Range("B12").Value returns. If foo happened to be Nothing at that point, run-time error 91 would be raised. If we added the Set keyword to the assignment, we would now be assigning the actual object reference itself. Wait, there’s more.
Dim foo As Variant
Set foo = Range("B12") ' foo becomes Variant/Range
foo = Range("B12") ' Variant subtype is only known at run-time '...
If foo is a Variant, it assigns Range("B12").Value (given multiple cells e.g. Range("A1:B12").Value, foo becomes a 2D Variant array holding the values of every cell in the specified range), but if we add Set in front of the instruction, foo will happily hold a reference to the Range object itself. But what if foo has an explicit value type?
Dim foo As String
Set foo = Range("B12") ' object required
foo = Range("B12") ' default member Get and implicit type conversion '...
If foo is a String and the cell contains a #VALUE! error, a run-time error is raised because an error value can’t be coerced into a String …or any other type, for that matter. Since String isn’t an object type, sticking a Set in front of the assignment would give us an “object required” compile error.
Add to that, that Range is either a member of a global-scope object representing whichever worksheet is the ActiveSheet if the code is written in a standard module, or a member of the worksheet itself if the code is written in a worksheet module, and it becomes clear that this seemingly simple code is riddled with assumptions – and assumptions are usually nothing but bugs waiting to surface.
See, “simple” code really isn’t all that simple after all. Compare to a less naive / more defensive approach:
Dim foo As Variant foo = ActiveSheet.Range("B12").Value
If Not IsError(foo) Then
Dim bar As String
bar = CStr(foo) '...
End If
Now prepending a Set keyword to the foo assignment no longer makes any sense, since we know the intent is to get the .Value off the ActiveSheet. We’re reading the cell value into an explicit Variant and explicitly ensuring the Variant subtype isn’t Variant/Error before we go and explicitly convert the value into a String.
Write code that speaks for itself:
Avoid implicit default member calls
Avoid implicit global qualifiers (e.g. [ActiveSheet.]Range)
Avoid implicit type conversions from Variant subtypes
Bang (!) Operator
When the default member is a collection class with a String indexer, VBA allows you to use the Bang Operator! to… implicitly access that indexer and completely obscure away the default member accesses:
Here we’re looking at ADODB.Recordset.Fields being the default member of ADODB.Recordset; that’s a collection class with an indexer that can take a String representing the field name. And since ADODB.Field has a default property, that too can be eliminated, making it easy to… completely lose track of what’s really going on.
Can Rubberduck help / Can I help Rubberduck?
As of this writing, Rubberduck has all the information it needs to issue inspection results as appropriate… assuming everything is early-bound (i.e. not written against Variant or Object, which means the types involved are only known to VBA at run-time).
In fact, there’s already an Excel-specific inspection addressing implicit ActiveSheet references, that would fire a result given an unqualified Range (or Cells, Rows, Columns, or Names) member call.
This inspection used to fire a result even when the code was written in a worksheet module, making it a half-lie: without Me. qualifying the call, Range("A1") in a worksheet module is actually implicitly referring to that worksheet…and changing the code to explicitly refer to ActiveSheet would actually change the behavior of the code. Rubberduck has since been updated to understand these implications.
Let-assignments involving implicit type conversions are also something we need to look into. Help us do it! This inspection also implies resolving the type of the RHS expression – a capability we’re just barely starting to leverage.
If you’re curious about Rubberduck’s internals and/or would love to learn some serious C#, don’t hesitate to create an issue on our repository to ask anything about our code base; our team is more than happy to guide new contributors in every area!
The release was going to include a number of important fixes for the missing annotation/attribute inspection and quick-fix, but instead we disabled it, along with a few other buggy inspections, and pushed the release – 7 months after 2.0.13, the last release was now over 1,300 commits behind, and we were reaching a point where we knew a “green release” was imminent, but also a point where we were going to have to make some more changes to parts of the core – notably in order to implement the fixes for these broken annotation/attribute inspections.
So we shipped what we had, because we wouldn’t jeopardize the 2.1 release with parser logic changes at that point.
Crossroads
By Hillebrand Steve, U.S. Fish and Wildlife Service [Public domain], via Wikimedia CommonsSo here we are, at the crossroads: with v2.1.0 released, things are going to snowball – there’s a lot on our plates, but we now have a solid base to build upon. Here’s what’s coming:
Castle Windsor IoC: hopefully-zero user-facing changes, we’re replacing good old Ninject with a new dependency injection framework in order to gain finer control over object destruction – we will end up correctly unloading!
That’s actually priority one: the port is currently under review on GitHub, and pays a fair amount of long-standing technical debt, especially with everything involving menus.
Annotation/Attributes: fixing these inspection, and the quick-fix that synchronizes annotations with module attributes and vice-versa, will finally expose VB module and member attributes to VBA code panes, using Rubberduck’s annotation syntax.
For example, adding '@Description("This procedure does XYZ") on top of a procedure will tell Rubberduck that you mean that procedure to have a VB_Description attribute; when Rubberduck parses that module after you synchronize, it will be able to use that description in the context status bar, or as tooltips in the Code Explorer.
IgnoreOnce: this quick-fix is supported by pretty much every single inspection, and means to insert an ‘@Ignore SomeInspectionNameannotation, but the current implementation has a bug that makes successive calls offset the insertion line, which obviously results in broken code.
This is considered a serious issue, because it affects pretty much every single inspection. Luckily there’s a [rather annoying and not exactly acceptable] work-around (apply the fix bottom-to-top in a module), but still.
But there’s a Greater Picture, too.
The 2.1.x Cycle
At the end of this development cycle, Rubberduck will:
Work in the VB6 IDE;
Have formalized the notion of an experimental feature;
Have a working Extract Method refactoring;
Make you never want to use the VBE’s Project References dialog ever again;
Compute and report various code metrics, including cyclomatic complexity and nesting levels, and others(and yes, line count too);
Maybe analyze a number of execution paths and implement some of the coolest code inspections we could think of;
Be ready to get really, really serious about a tear-tab AvalonEdit code pane.
If all you’re seeing is Rubberduck’s version check, the next version you’ll be notified about will be 2.1.2, for which we’re shooting for 2017-11-13. If you want to try every build until then (or just a few), then you’ll want to keep an eye on our releases page!
But shipping “thank you” packages to the project’s contributors isn’t. I need your help!
You use Rubberduck? You like what we’re doing? Over the few years the project has been running we’ve received extremely motivating positive feedback, tons of feature requests, and over 420 virtual hugs GitHub stars. And we still get that warm fuzzy every time.
Without Rubberduck’s contributors, we wouldn’t be anywhere near where we are today. There wouldn’t be over 50 implemented code inspections, the parser/resolver core would still be terribly slow and approximate, the Smart Indenter port wouldn’t be completed, there would be nobody to work on and fix the source control integration feature; there wouldn’t be a German translation, a regular expression analyzer tool, and so on: the project’s contributors are the real wizards shaping a dream into a reality… and I want to thank them for that, on behalf of all our users, stargazers and followers.
I can’t do this alone, so I started a GoFundMe campaign to collect enough funds to get some Rubberduck swag made and shipped to the project’s contributors.
During the first 24 hours of the campaign, $365 were donated by only 5 contributors – so I decided to match that amount (little bit more actually) and proceeded to order some of the stuff – as of now the campaign is only 30% raised though.
So what’s the actual swag?
The Rubberduck tee has the project’s name and website on the front, and the GitHub repository URL on the back:
Rubberduck Tee (Front)
Rubberduck Tee (Back)
The Rubberduck mug has the same assets, on white and black backgrounds. Both the tees and the mugs are ordered from SpreadShirt:
Rubberduck Mug (Black)
Rubberduck Mug (White)
There’s more to the thank you packages, but I’d like to try to keep the rest a surprise… so I’m not saying anything else about it!
Nice! Can I haz a mug?
Simple: contribute to Rubberduck, and help us bring the VBE into this century! …actually, once I have the packages ready to ship (and the funds to ship them!), I’ll know how much overstock I’m left with (if any). Expect the biggest donators to get a little something too, and if there’s still some left I might run a little contest among Rubberduck users and supporters, so… stay tuned!
Last time I went over the startup and initialization of Rubberduck, and I said I was going to follow it up with how the parser and resolver work.
Just so happens that Max Dörner, who has pretty much owned the parser and resolver parts of Rubberduck since he joined the project (that’s right – jumped head-first into some of the toughest, most complicated code in the project!), has nicely documented the highlights of how parsing and resolving works.
So yeah, all I did here was type up an intro. Buckle up, you’re in for a ride!
Part 2: Parsing & Resolving
Rubberduck processes the code in all unprotected modules in a five-step process. First, in the parser state Pending, the projects and modules to parse are determined. Then, in the parser state LoadingReferences, the references currently used by the projects, e.g. the Excel object model, and some built-in declarations are loaded into Rubberduck. Following this, the actual processing of the code begins. Between the parser states Parsing and Parsed the code gets parsed into parse trees with the help of Antlr4. Following this, between the states ResolvingDeclarations and ResolvedDeclarations the module, method and variable declarations are generated based on the parse tree. Finally, between the states ResolvingReferences and Ready the parse trees are walked a second time to determine the references to the declarations within the code.
At each state change, an event is fired which can be handled by any feature subscribing to it, e.g. the CodeExplorer, which listens for the state change to ResolvedDeclarations.
A More Detailed Story
The entry point for the parsing process is the ParseCoordinator inside the Rubberduck.Parsingassembly. It coordinates the parsing process and is responsible for triggering the appropriate state changes at the right time, for which it uses a IParserStateManager passed to it. To trigger the different stages of the parsing process, the ParseCoordinator uses a IParsingStageService. This is a facade passed to it providing a unified interface for calling the individual stages, which are all implemented in an individual set of classes. Each has a concurrent version for production and a synchronous one for testing. The latter was needed because of concurrency problems of the mocking framework.
General Logistics
Every parsing run gets executed in fresh background task. Moreover, to always be in a consistent state, we allow only one parsing run to execute at a time. This is achieved by acquiring a lock in a top level method. This top level method is also the point at which any cancellation or unexpected exception will be caught and logged.
The first step of the actual parsing process is to set the overall parser state to Pending. This signals to all components of Rubberduck that we left a fully usable state. Afterwards, we refresh the projects cache on the RubberduckParserState asking the VBE for the loaded projects and then acquire a collection of the modules currenlty present.
Loading References
After setting the overall parser state to LoadingReferences, the declarations for the project references, i.e. the references selected in Tools –> References... , get loaded into Rubberduck. This is done using the ReferencedDeclarationsCollector in the Rubberduck.Parsing.ComReflectionnamespace, which reads the appropriate type libraries and generates the corresponding declarations.
Note that the order in the References dialog determines what procedure or field an identifier resolves to in VBA if two or more references define a procedure or field of the same name. This prioritization is taken into account when loading the references.
Unfortunately, we are currently not able to load all built-in declarations from the type libraries: there are some hidden members of the MSForms library, some special syntax declarations like LBound and everything related to Debug, and aliases for built-in functions like Left, where Leftis the alias for the actual hidden function defined in the VBA type library. These get loaded as a set of hand-crafted declarations defined in the Rubberduck.Parsing.Symbols.DeclarationLoadersnamespace.
Parsing the Code
At the start of the processing of the actual code, the parser state is set to Parsing. However, this time this is achieved by setting the individual modules states of the modules to be parsed and then evaluating the overall state.
Each module gets parsed separately using an individual ComponentParseTask from the Rubberduck.Parsing.VBA namespace, which is powered by the Antlr4 parser generator. The end result is a pair of two parse trees providing a structured representation of the code one time as seen in the VBE and one time as exported to file.
The general process using Antlr is to provide the code to a lexer that turns the code into a stream of tokens based on lexer rules. (The lexer rules used in Rubberduck can be found in the file VBALexer.g4 in the Rubberduck.Parsing.Grammar namespace.) Then this token stream gets processed by a parser that generates a parse tree based on the stream and a set of parser rules describing the syntactic rules of the language. (The VBA parser rules used in Rubberduck can be found in the file VBAParser.g4 in the Rubberduck.Parsing.Grammar namespace. However, there are more specialized rules in the project). The parse tree then consists of nodes of various types corresponding to the rules in the parser rules.
Even when counting the Antlr workflow described above as one step, the actual parsing process in the ComponentParseTask is a multi stage process in itself. This has two reasons: there are precompiler directives in VBA and some information regarding modules is hidden from the user inside the VBE, namely attributes.
The precompiler directives in VBA allow to conditionally select which code is alive. This allows to write code that would only be legal VBA after evaluating the conditional compilation directives. Accordingly, this has to be done before the code reaches the parser. To achieve this, we parse each module first with a specialized grammar for the precompiler directives and then hide all tokens that are dead after the evaluation from the VBA parser, including the precompiler directives themselves, by sending the tokens to a hidden channel in the tokenstream. Afterwards, the dead code is still part of the text representation of the tokenstream by disregarded by the parser.
To cover both the attributes, which are only present in the exported modules, and provide meaningful line numbers in inspection results, errors and the command bar, we parse both the attributes and the code as seen in the VBE code pane into a separate parse tree and save both on the ModuleState belonging to the module on the RubberduckParserState.
One thing of note is that Antlr provides two different kinds of parsers: the LL parser that basically parses all valid input for every not indirectly left-recursive grammar (our VBA grammar satisfies this) and the SLL parser, which is considerably faster but cannot necessarily parse all valid input for all such grammars. Both parsers are guaranteed to yield the same result whenever the parse succeeds at all. Since the SLL parser works for next to all commonly encountered code, we first parse using it and fall back to the LL parser if there is a parser error.
Following the parse, the state of the module is set to Parsed on a successful parse and to ParserError, otherwise. After all modules have finished parsing, the overall parser state is evaluated. If there has been any parser error, the parsing process ends here.
Resolving Declarations
After parsing the code into parse trees, it is time to generate the declarations for the procedures, functions, properties, variables and arguments in the code.
First, the state of all modules gets set to ResolvingDeclarations, analogous to the start of parsing the code. Then the tree walker and listener infrastructure of Antlr is used to traverse the parse trees and generate declarations whenever the appropriate grammar constructs are encountered. This is done inside the implementations of IDeclarationResolveRunner in the Rubberduck.Parsing.VBAnamespace.
Note that there is still some information missing on the declarations at this point that cannot be determined in this first pass over the parse trees. E.g. the supertypes of classes implementing the interface of another class are not known yet and, although the name of the type of each declaration is already known, the actual type might not be known yet. For both cases we first have to know all declarations.
After the parse trees of all modules have been walked, the overall parser state gets set to ResolvedDeclarations, unless there has been an error, which would result in the state ResolverError and an immediate stop of the parsing run.
Resolving References
After all declarations are known, it is possible to resolve all references to these declarations within the code, beit as types, supertypes or in expressions. This is done using the implementations of IReferenceResolveRunner in the Rubberduck.Parsing.VBA namespace.
First, the state of the modules for which to resolve the references gets set to ResolvingReferencesand the overall state gets evaluated. Then the CompilationPasses run. In these the type names found when resolving the declarations get resolved to the actual types. Moreover, the type hierarchy gets determined, i.e. super- and and subtypes get added to the declarations based on the implements statements in the code.
After that, the parse trees get walked again to find all references to the declarations. This is a slightly complicated process because of the various language constructs in VBA. As a side effect, the variables not resolving to any declaration get collected. Based on these, new declarations get created, which get marked as undeclared. These form the basis for the inspection for undeclared variables.
After all references in a module got resolved, the module state gets set to Ready. If there is some error, the module state gets set to ResolverError. Finally, the overall state gets evaluated and the parsing run ends.
Handling State Changes
On each change of the overall state, an event is raised to which other features can subscribe. Examples are the CodeExplorer, which refreshes on the change to ResolvedDeclarations, and the inspections, which run on the change to Ready.
Handling any state change but the two above is discouraged, except maybe for the change to Pending or the error states if done to disable things. The problem with the other states is that they may never be encountered during a parsing run due to optimizations. Moreover, Rubberduck is generally not in a stable state between Pending and ResolvedDeclarations. Features requiring access to references should generally only handle the Ready state.
Events also get raised for changes of individual module states. However, it should be preferred to handle overall state changes because module states change a lot, especially in large projects.
IMPORTANT: Never request a parse from a state change handler! That will cancel the current parse right after the handlers for this state in favor of the newly requested one.
Doing Only What Is Necessary
When parsing again after a successful parsing run, the easiest way to proceed is to throw away all information you got from the last parsing run and start from scratch. However, this is quite wasteful since typically only a few modules change between parsing runs. So, we try to reuse as much information as possible from prior parsing runs. Since our VBA grammar is build for parsing entire modules the smallest unit of reuse of information we can work with is a module.
We only reparse modules that satisfy one of three conditions: they are new, modified, or not in the state Ready. For the first two conditions it should be obvious why we have to reparse such modules. The question is rather how we evaluate these conditions.
To be able to determine whether a module has changed, we save a hash of the code contained in the module whenever the module gets parsed successfully. At the start of the parsing run, we compare the saved hash with the hash of the corresponding freshly loaded component to find those modules with modified content. In addition we save a flag on the module telling us whether the content hash has ever been saved. If this is not the case, the module is regarded as new.
For the third condition the question is rather why we also reparse such modules. The reason is that such modules might be in an invalid state although the content hash had been written in the last parsing run. E.g. they might have encountered a resolver error or they got parsed successfully in the last parsing run, but the parsing run got cancelled before the declarations got resolved. In these cases the content hash has already been saved so that the module is neither considered to be new nor modified. Consequently, it would not be considered for parsing and resolving if only modules satisfying one of the first two conditions were considered. Because of the possibility of such problems, we rather err on the save side and reparse every module that has not reached the success state Ready.
Since reparsing makes all information we previously acquired about the module invalid, we have to resolve the declarations anew for the modules we reparse. Fortunately, the base characteristics of a declaration only depend on the module it is defined in. So, we only have to resolve declarations for those modules that get reparsed. For references the situation is more complicated.
Since all declarations from the modules we reparse get replaced with new ones, all references to them, all super- and subtypes involving the reparsed modules and all variable and method types involving the reparsed modules are invalid. So, we have to re-resolve the references for all modules that reference the reparsed modules. To allow us to know which modules these are we save the information which module references which other modules in an implementation of IModuleToModuleReferenceManager accessed in the ParseCoordinator via the IParsingCacheService facade. This information gets saved whenever the references for all modules have been resolved successfully, even before evaluating the overall parser state.
In addition to the modules that reference modules that got reparsed, we also re-resolve those modules that referenced modules or project references having just been removed. This is necessary because the references might now point to different declarations. In particular, a renamed module is treated as unrelated to the old one. This means that renaming a module looks to Rubberduck like the removal of the old module and the addition of a new module with a new name.
The final optimization in place on a reparse is that we do not reload the referenced type libraries or the special built-in declarations every time. We just reload those we have not loaded before.
Caching and Cache Invalidation
If you have read the previous paragraph, you might have already realized that the additional speed due to only doing what is necessary comes at a cost: various types of cached data get invalid after parsing and resolving only some modules. So we have to remove the data at a suitable place in the parsing process. To achieve this the ParseCoordinator primarily calls different methods from the IParsingCacheService facade handed to it.
In the next sections we will work our way up from cache data for which you would probably seldom realize that we forgot to remove it to data for which forgetting to remove it sends the parser down in flames. After that, we will finish with a few words about refreshing the DeclarationFinder on the RubberduckParserState.
Invalid Type Declarations
The kind of cache invalidation problem you would probably not realize is that the type as which a variable is defined has to be replaced in case it is a user defined class and the class module gets reparsed; it now has a different declaration. This would probably just cause some issues with some inspections because the actual IdentifierReference tying the identifier to the class declaration is not related to the type declaration we save. Fortunately, the TypeAnnotationPass works by replacing the type declaration anyway. So, we just have to do that for all modules for which we resolve references.
Invalid Super- and Subtypes
As mentioned in the section about resolving references, we run a TypeHierarchyPass to determine the super- and subtypes of each class module (and built-in library). After reparsing a module, we have to re-resolve its supertypes. However, we also have to remove the old declaration of the module itself from the supertypes of its subtypes and from the subtypes of its supertypes, which has some further data invalidation consequences. Otherwise, the “Find all Implementations” dialog or the rename refactoring might produce …interesting results for the affected modules.
The removal of the super- and subtypes is performed via an implementation of ISupertypeCleareron all modules we re-resolve, including the modules we reparse, before clearing the state of the modules to be reparsed. Here, a removal of the supertypes is sufficient because everything is wired up such that manipulating the supertypes automatically triggers the corresponding change on the subtypes.
Invalid Module-To-Module References
As with all other reference caches, part of our cache saving which module references which other modules can become invalid when we re-resolve a module; it might just be that the the part referencing another module is gone. Fortunately, the way these references are saved does not depend on the actual declarations. So reparsing alone does not cause problems. This allows us to defer the removal of the module-to-module references to the reference resolver.
Being able to postpone the removal until we resolve references is fortunate because of potential problems with cancellations. We use the module-to-module references to determine which modules need to be re-resolved. If they got removed and the parsing run got cancelled before they got filled again in the reference resolver, we would potentially miss modules we have to re-resolve. Then the user would need to modify the affected modules in order to force Rubberduck to re-resolve them.
To handle this problem, the reference resolver itself has a cache of the modules to resolve, which is only cleared at the very end of its work. This is safe because the reference resolver only ever processes modules for which it can find a parse tree on the RupperduckParserState.
Invalid References
Invalid IndentifierReferences to declarations from previous parsing runs can cause any number of strange behaviors. This can range from selections referring to references that have once been at that line and column but having been removed in the meantime to refactorings changing things they really should not change.
It is rather clear that the references from all modules to be re-resolved should be removed. However, this is not as straightforward as it seems. The problem is that the references live in a collection on the referenced declaration and not in a collection attached to the module whose code is referencing the declaration. In particular, this makes it easy to forget to remove references from built-in declarations. To avoid such issues, we extracted the logic for removing references by a module into implementations of IReferenceRemover, which is hidden behind the IParsingCacheService facade.
Modules And Projects That No Longer Exist
Now we come to the piece where everything falls to pieces if we are not doing our job, modules and projects that get removed from the VBE. The problem is that some functionality like the CodeExplorer has to query information from the components in the VBE via COM Interop. If a component does no longer exist when the information gets queried, the parsing run will die with a COMException and there is little we can do about that. So we have to be careful to remove all declarations for no longer existing components right at the start of the parsing run.
To find out which modules no longer exist, we simply collect all the modules on the declarations we have cached and compare these to the modules we get from the VBE. More precisely, we compare the identifiers we use for modules, the QualifiedModuleNames. This will also find modules that got renamed. Projects are bit more tricky since they are usually treated as equal if their ProjectIds are the same; we save these in the project help file. Thus, we have to take special care for renamed projects. Knowing the removed projects, their modules get added to the removed modules as well.
Removing the data for removed modules and projects is a bit more complicated than for modules that still exist. After their declarations got removed, there is no sign anymore that they ever existed. So, we have to take special care to remove everything in the right order to guarantee that all information is gone already when we erase the declaration; after each step, the parsing run might be cancelled.
The final effect of removing modules is that the modules referencing the removed modules need to be re-resolved. Intuitively one might think that this will always result in a resolver error. However, keep in mind that renaming is handled as removing a module and adding another. Then the references will simply point to the new renamed module. Because of possible cancellations on the way to resolving the references, we immediately set the state of the modules to be re-resolved to ResolvingReferences. This has the effect that they will be reparsed in case of a cancellation.
Note that basically the same procedure is also necessary whenever we reload project references. Accordingly, we do this right after unloading the references, without allowing cancellations in between.
Refreshing the DeclarationFinder
Since declarations and references change in nearly all steps of the parsing process, we have to refresh our primary cached source of declarations, the DeclarationFinder, quite regularly when parsing. Unfortunately, this is a rather computation intensive thing to do; a lot of dictionaries get populated. So, we refresh only if we need to. E.g. we do not refresh after loading and unloading project references in case nothing changed. However, there are two points in each parsing run where we always have to refresh it: before setting the state to ResolvedDeclarations and before evaluating the overall state at the end of the parsing run, which results in the Ready state in the success path.
Refreshing before the change to ResolvedDeclarations is necessary to ensure that removed modules vanish from the DeclarationFinder before the handlers of this state change event run, including the CodeExplorer. We have to refresh again at the end because, from inside the ParseCoordinator, we can never be sure that the reference resolver did not do anything; it has its own cache of modules that need to be resolved.
One optimization done in the DeclarationFinder itself is that some collections are populated lazily, in particular those dealing only with built-in declarations. This saves the time to rebuild the collections multiple times on each parsing run. However, there is a price to pay. The primary users of the DeclarationFinder are the reference resolver and the inspections, both of which are parallelized. Accordingly, it can happen that multiple threads race to populate the collections. This is bad for the performance of the corresponding features. So, we make compromises by immediately populating the most commonly used collections.